Skip to content
Anika Yadav
Technical Product ManagerSanta Clara, CAOpen to new work

I make sense of messy things.

I investigate questions that don’t have clean answers, build AI-powered tools that earn their place, and turn what I find into something a person can actually use. Currently doing that for payments infrastructure at Velaura AI.

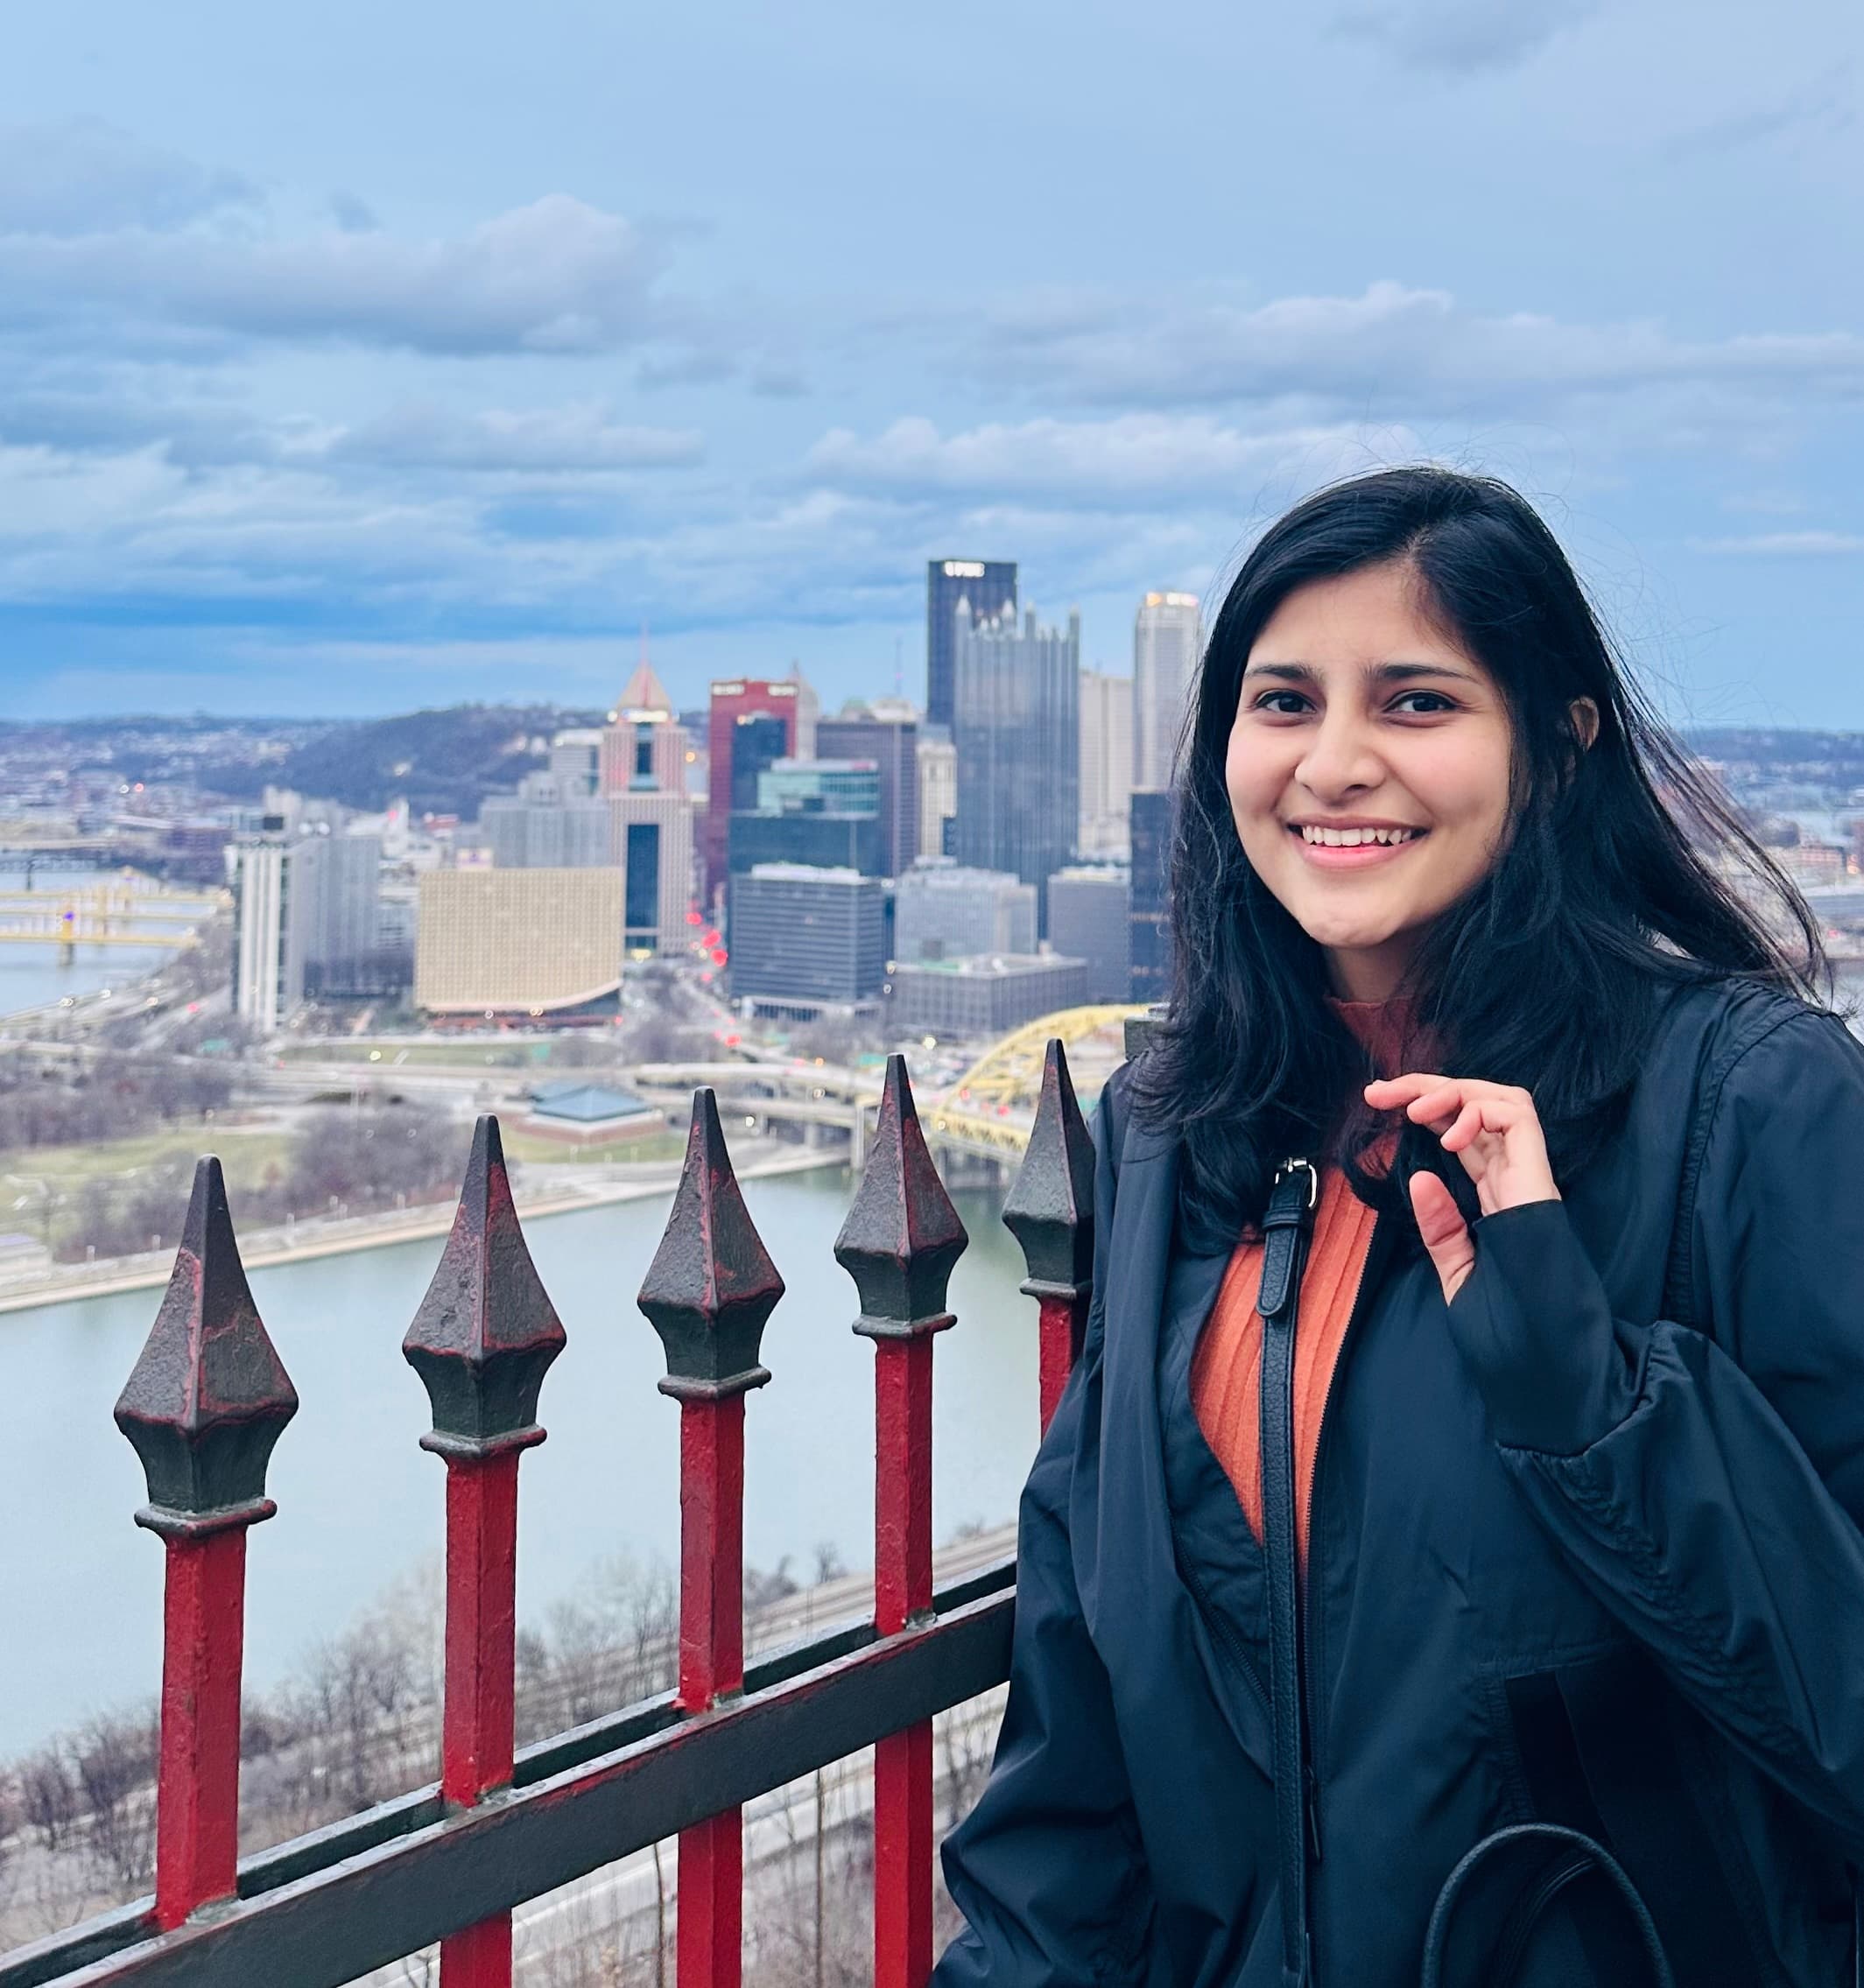
Anika Yadav, portrait
Anika YadavUsually mid-investigation.
01Selected work

Three things I built properly.

012025AI

Agentic Payments Layer

Problem
Enterprise finance teams were approving stablecoin payments by hand — every routing decision, every policy check, a person in a queue.
Built
An agent that reads payment intent in plain language, checks it against enterprise policy, picks a settlement route, and executes over AP2/X402/A2A.
My part
Product lead — architecture, policy model, agent guardrails, rollout
~40% faster processingwith no manual intervention in the approval path

LLM agents · Policy engine · Stablecoin rails

022024Experiment

Grading Assistant

Problem
Professors spent more time writing the same feedback than teaching. Generic AI grading was worse than useless — confidently wrong, and it showed.
Built
A retrieval pipeline with per-student memory, tuned chunking, and an LLM-as-judge gate that blocked any release scoring below the bar.
My part
AI/ML product lead — retrieval design, eval harness, faculty research
3.2 → 4.5 CSATadopted by 10+ professors after 50 interviews

RAG · Golden datasets · LLM-as-judge

032023Data

Visual Procurement Pipeline

Problem
Expedia had 200K+ user-uploaded property photos and no reliable way to tell which ones were worth putting in front of a traveler.
Built
An ML pipeline chaining object detection, scene classification, and a quality model — scoring every upload for catalogue eligibility.
My part
Product manager — model requirements, quality thresholds, rollout
+2.5% conversion83K catalogue entries, ~$25M revenue impact

Computer vision · Scene classification · Ranking

Full case studies in progress — ask me about any of these.

02The lab

Smaller questions, faster answers.

Short experiments with a question, a method, and an honest result — including the ones that didn’t work.

  • EXP 01mostly confirmed

    Can an LLM detect a misleading chart?

    Hypothesis
    It will catch truncated axes but miss cherry-picked time ranges.
    Tried
    Fed 60 charts — half sound, half subtly manipulated — to a vision model and asked it to flag the distortion and name it.

    Caught 88% of truncated axes. Caught 31% of cherry-picked ranges.

  • EXP 02confirmed

    How much does retrieval quality actually move the needle?

    Hypothesis
    Better chunking beats a bigger model.
    Tried
    Held the model fixed, varied chunk size and overlap across 200 research questions.

    Chunking changes swung answer accuracy 22 points. Model size swung it 6.

  • EXP 03confirmed

    Can AI reliably extract structure from messy documents?

    Hypothesis
    Schema-constrained output will handle everything except missing fields.
    Tried
    Ran 80 inconsistent invoices through a strict schema with a validation-error retry loop.

    76/80 clean on first pass. The 4 failures were genuinely absent data.

  • EXP 04in progress

    Ask my portfolio anything.

    Hypothesis
    A grounded chatbot beats making you read six pages to find one answer.
    Tried
    Scoped the retrieval index, the citation rule, and the refusal behaviour. Not built yet.

    In progress — shipping when it can cite every claim it makes.

  • EXP 05confirmed

    Do “AI” job postings actually require AI skills?

    Hypothesis
    “AI” is doing positioning work in the title, not requirement work in the body.
    Tried
    Pulled 2,400 postings with “AI” in the title across 6 job families, then hand-coded every requirements section for concrete, named AI skills.
    Didn’t expect
    Product roles were the worst offenders — and the ones that did name a skill overwhelmingly named prompt writing, not evaluation.

    Only 34% named a single concrete AI skill in their requirements.

    • Research81%
    • Engineering64%
    • Data47%
    • Design29%
    • Product22%
    • Marketing14%

    Share of “AI” postings naming a concrete AI skill, by job family

    34% average

    Dataset
    2,400 postings · 6 job families · Jan–Jun 2026
    Method
    Keyword match on title · manual coding of requirements
04How I think
  1. 01

    AI should earn its place.

    The best version of most features has no model in it. I reach for AI when the alternative genuinely can’t do the job — not because it’s available.

  2. 02

    Show your evidence.

    A claim without its working is decoration. Every number on this site can be traced to how it was measured.

  3. 03

    Measure before you marvel.

    Demos are easy and misleading. I build the eval set before the prompt, so “it feels better” has to survive contact with a number.

  4. 04

    Make complexity understandable.

    If I can’t explain the tradeoff to the person who has to live with it, I don’t understand it well enough to ship it.

05About

I started as an engineer building computer vision and NLG pipelines, moved into product, and never lost the habit of opening the hood.

That’s the whole thing, really. I’m close enough to the system to know what a tradeoff actually costs, and far enough back to keep asking whether we should be building it at all. These days that means agentic payments infrastructure by day, and a running notebook of investigations by night.

Previously

  • Velaura AITechnical Product ManagerPresent
  • Prof AssistAI/ML Product Manager2024
  • Expedia GroupProduct Manager2021–23
  • Times InternetSoftware Engineer2019–21

Studied

  • Carnegie Mellon UniversityMS Product Management2024
  • KIITB.Tech, Computer Science2019

Currently exploring

  • Evaluation harnesses that survive contact with production
  • Where LLM-as-judge quietly stops working
  • Data journalism as a product discipline
  • Tokenized deposits on permissioned networks

At the moment

Reading
The Art of Doing Science and Engineering
Open tabs
far too many
Current bug
off-by-one, probably

Have a messy question?

AI products, agentic systems, payments infrastructure, or a dataset nobody’s looked at properly yet. I’d like to hear about it.

anika.yadav.work@gmail.com